Why “more context” stops helping after a while
You’ve seen the pattern: a conversation that starts crisp becomes sluggish and oddly forgetful after a few dozen turns. Adding more transcript feels like it should help, but it often lowers signal-to-noise. The model has to “pay attention” across more competing details—old requirements, tentative ideas, side jokes, and corrected facts—and important constraints stop standing out.
More context also increases the chance of internal contradictions. If earlier messages say “ship Friday” and later ones say “ship Monday,” the assistant may blend them, or pick the wrong one, especially if both appear credible. Even when it answers correctly, long prompts cost more, run slower, and are harder to debug because failures become difficult to reproduce and explain.
What to remember: goals, facts, preferences, or logs?
Picture a returning user who says, “Same as last time.” If you only saved the transcript, you’ll replay noise. If you saved nothing, you’ll ask obvious questions again. The useful split is: goals (what they’re trying to achieve), facts (stable constraints like account type or technical environment), preferences (format, tone, defaults), and logs (what happened in prior sessions). Each behaves differently over time, so “store everything” is the wrong default.
Goals deserve the highest priority but the shortest shelf life: people change projects and deadlines. Facts can be durable, but only if you can verify them or tag them with a source and date. Preferences are lightweight and high-leverage, yet easy to overgeneralize (“likes short answers” isn’t universal). Logs are the most tempting and the most dangerous: they’re bulky, privacy-sensitive, and often irrelevant unless you can retrieve only the few events that explain the current request.
When memory goes bad: staleness, duplication, and hallucinated facts
A familiar failure shows up when a user returns weeks later: the assistant confidently applies last month’s goal to today’s request. That’s staleness, and it spreads because “memory” tends to be written once and reused many times. If you can’t answer “when was this true?” you’ll treat expired plans, old tooling choices, or past team decisions as current, even when the live conversation is signaling a change.
Duplication is quieter but just as corrosive. The same preference gets saved three different ways (“brief,” “no fluff,” “bullets”), or a fact is copied into multiple summaries, so retrieval brings back a chorus of near-identical notes. That inflates importance, crowds out newer details, and makes conflicts harder to detect. Then the worst case: hallucinated facts in memory. A model infers a detail (“uses Stripe,” “prefers TypeScript”) and it gets stored like a user-provided truth. Once written, it’s hard to unwind without explicit verification, audit trails, and a willingness to say “I’m not sure.”
Three practical architectures for long-term context
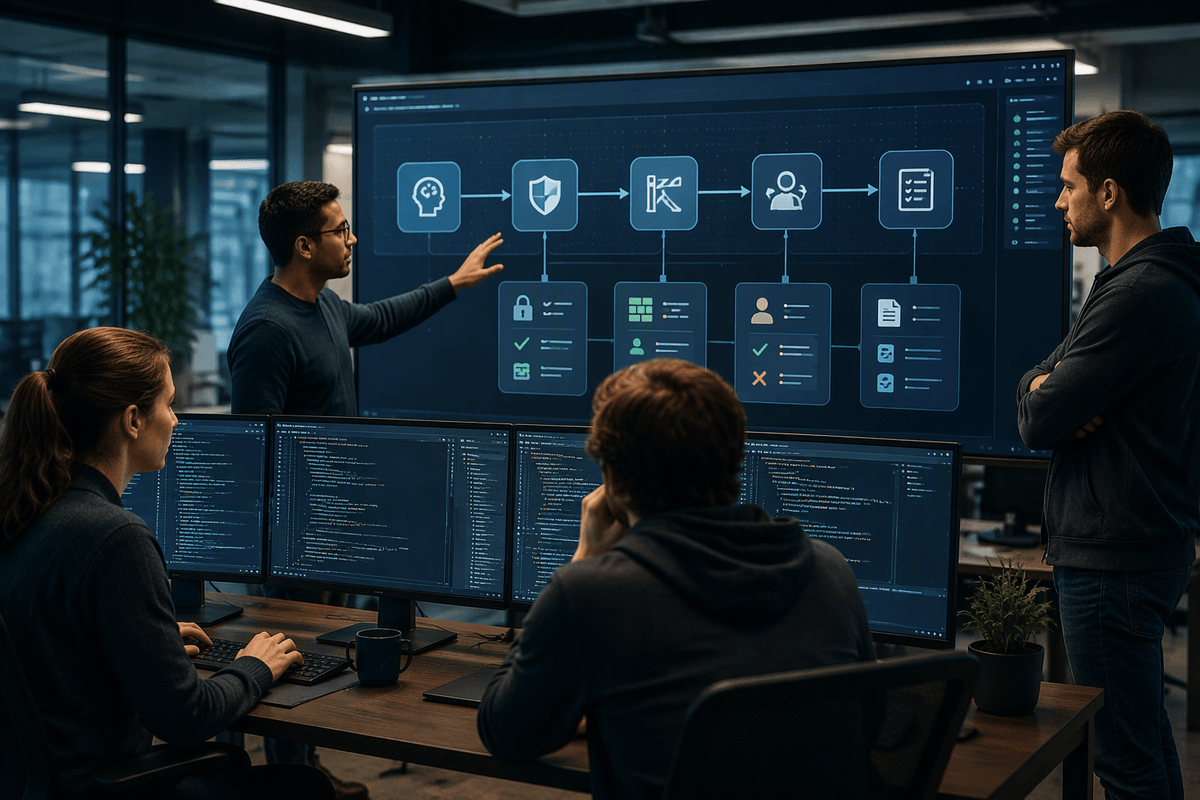
A common starting point is a “working set” prompt: a short rolling summary plus a small set of pinned items (current goal, key constraints, and a few preferences). It’s simple, cheap to run, and easy to reason about because everything the model sees is explicit. The trade-off is brittleness: if the summary misses a nuance, or a pinned fact goes stale, the assistant will stay consistently wrong until someone edits it. This approach works best when you can attach dates, owners, and a habit of re-confirming anything that affects decisions.
The second pattern is retrieval: keep memories outside the prompt, index them (often with embeddings), and fetch only the top few that match the current turn. Done well, this prevents transcript bloat and lets you store rich logs without drowning the model. You need metadata, filtering, and tests so “similar” doesn’t mean “relevant,” plus privacy controls and deletion. The third pattern is a structured memory ledger: separate tables for user profile, project state, and verified facts, with an append-only event stream for what changed and when. It’s the most work up front, but it gives you conflict handling, auditability, and clearer rules for what can safely persist.
Keeping memory relevant: scoring, decay, and conflict rules
In practice, relevance isn’t a yes/no decision; it’s a score you maintain. Treat each memory item like a candidate in a queue with simple features: recency (last confirmed date), scope (applies to this project or “always”), confidence (user-stated vs inferred), and impact (changes output materially vs nice-to-have). Retrieval can then rank by score and hard-filter by scope and privacy class, so “preferred bullet points” can survive while “launch plan for Q1” naturally falls out.
Decay is how you keep the queue from turning into a museum. Set different half-lives: goals decay fast, preferences slower, verified facts slowest, and raw logs fastest unless they’re tagged as milestones. Conflict rules should be explicit: newer beats older only when the source is comparable, and anything that changes commitments (dates, budgets, tech stack) triggers a re-confirmation question. This adds friction and occasionally annoys users, but it prevents quiet, expensive drift.
Summarization that doesn’t erase what matters
Teams often summarize by “compressing the transcript,” then wonder why the assistant loses the one detail that made the answer correct. The fix is to summarize by category and purpose, not by chronology. Keep separate, small blocks for current goal, hard constraints, decisions made, open questions, and user preferences. Each block should carry a “last confirmed” date and, when possible, a source tag like user-stated, system-derived, or inferred (and treat inferred as provisional).
Good summaries also preserve disagreement. If a date changed twice, don’t pick one—store both with timestamps and mark the latest as tentative until confirmed. For logs, summarize outcomes and deltas, not conversation texture: “Chose Redis for rate limiting” beats “Talked about caching.” You need rewrite rules, tests, and occasional human review, because automatic summaries can quietly remove qualifiers (“only for this project”) that later matter most.
A simple plan to implement and measure memory quality
A familiar rollout is a “memory MVP” that you can observe: start with a short working set (goal, constraints, preferences), a small retrieval store, and a hard rule that nothing inferred becomes persistent without user confirmation. Add metadata you can query later: last-confirmed date, scope (project vs global), confidence, and deletion class. Build two offline test sets: (1) “returning user” scripts where key facts change midstream, and (2) “conflict” scripts with near-duplicates and reversals.
Measure outcomes, not vibes: reduce follow-up questions without increasing wrong commitments. Track stale-memory incidents, contradiction rates, and “asked to forget” compliance. Budget time for weekly audits of the top retrieved items; retrieval drift is a real operating cost, and it will show up first in support tickets, not dashboards.